model fatıgue
First look

Sonnet 5.5 is cheaper than Sonnet 5, until you turn it up to max

Published 29 Sep 2026Our test: one painting job

Pressing play loads YouTube's player (privacy-enhanced mode).

This is the video written out, with every figure in full, each linked to its source in the table below.

Two claims about the same model▶ 0:00

We gave two models the same prompt and the same picture, each on the effort setting Claude Code gives it by default: high for the older Sonnet 5, medium for Sonnet 5.5. Sonnet 5 wrote 66,874 output tokens to paint it. Sonnet 5.5 wrote 10,660. That's one run each, on a test we built, and it fits what Anthropic said at launch on 28 September, that Sonnet 5.5 "typically needs far fewer tokens to do the same work."

About half an hour after Anthropic's post, Artificial Analysis published a number pointing the other way. By its count, Sonnet 5.5 at max effort uses more output tokens per task than any model it has measured, ~193k, and costs 49% more per task than Sonnet 5. Both numbers are right. Which one applies to you depends on one setting, called effort.

The basics▶ 1:00

Sonnet 5.5 is the middle model of Anthropic's 5.5 family. Opus 5.5 came out the week before, and Anthropic says a Haiku 5.5 will join "in the coming weeks". You can use Sonnet 5.5 in the Claude apps, in Claude Code and on the API, including through Amazon's, Google's and Microsoft's clouds.

It costs the same per token as Sonnet 5: $2 per million input tokens and $10 per million output tokens, half of Opus 5.5's $4 and $20. Anthropic says it writes its output 30%+ faster than Sonnet 5.

Its headline score on Terminal-Bench 4.0, an agentic coding test, is 70.6%, where Sonnet 5 scored 10.3%. On GDPval-AA, a test of office work that is scored like a chess rating, it rates 1844 against Opus 5.5's 1846. Two independent evaluators, both running it at max, rank it second behind Opus 5.5: Artificial Analysis on its Intelligence Index, and Vals AI, where it scores 69.22% against Opus 5.5's 69.69%, a gap inside Vals's own ±0.96 margin, and places #2 of 66. Anthropic itself says "Opus 5.5 remains clearly stronger at complex, open-ended work requiring sustained judgment."

The setting behind the headline scores▶ 2:07

Like other recent Claude models, Sonnet 5.5 has five effort levels: low, medium, high, xhigh (extra high) and max. Effort controls how much the model reasons and how thoroughly it works, and you can change it. The Claude apps and Claude Code start it on medium, and the API starts it on high.

Anthropic ran its headline scores at max. One step down, at xhigh, the system card puts the GDPval-AA rating at 1725, with about 67% fewer output tokens than at max. On Terminal-Bench 4.0, Anthropic's table puts Sonnet 5.5 at max 4.2 points ahead of Opus 5.5 at xhigh, 70.6% against 66.4%. The system card gives those scores standard errors of ±2.5 and ±2.6 points, which makes a gap of that size too small to call.

In 10% of Opus 5.5's trials on that test, a request flagged by Anthropic's safeguards was answered by an older model instead. For Sonnet 5.5 it was 1.5% of trials. Anthropic says this likely lowered Opus 5.5's score.

Our test: the Great Wave, in code▶ 3:17

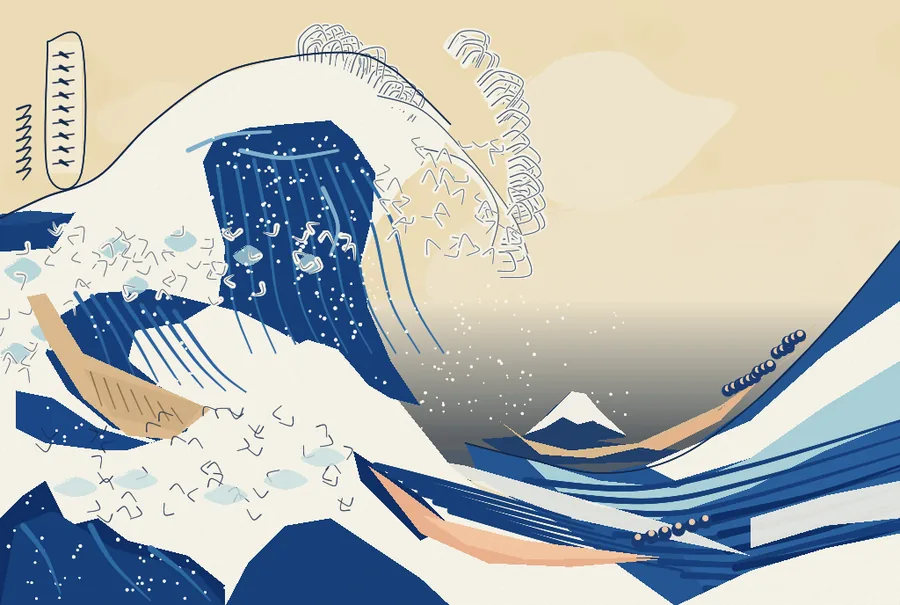
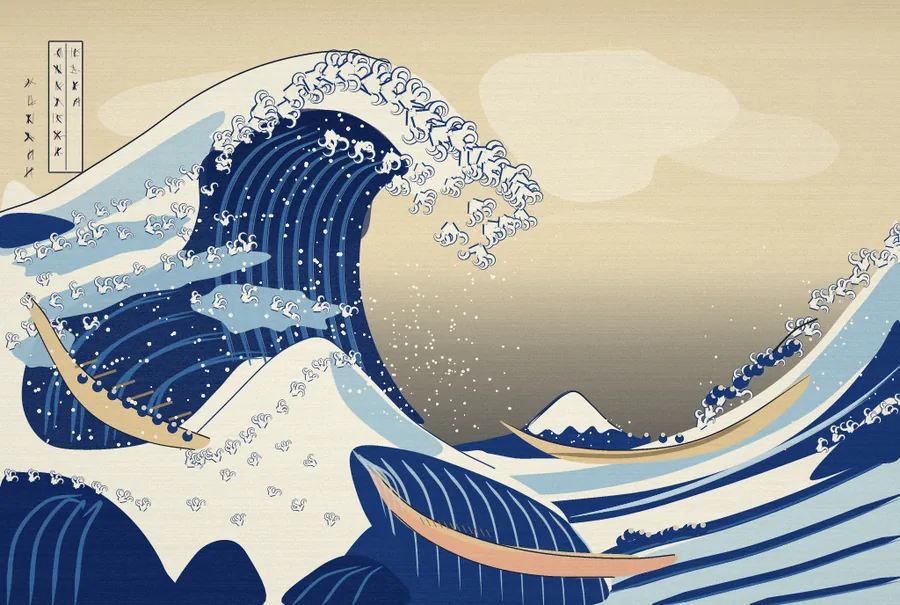
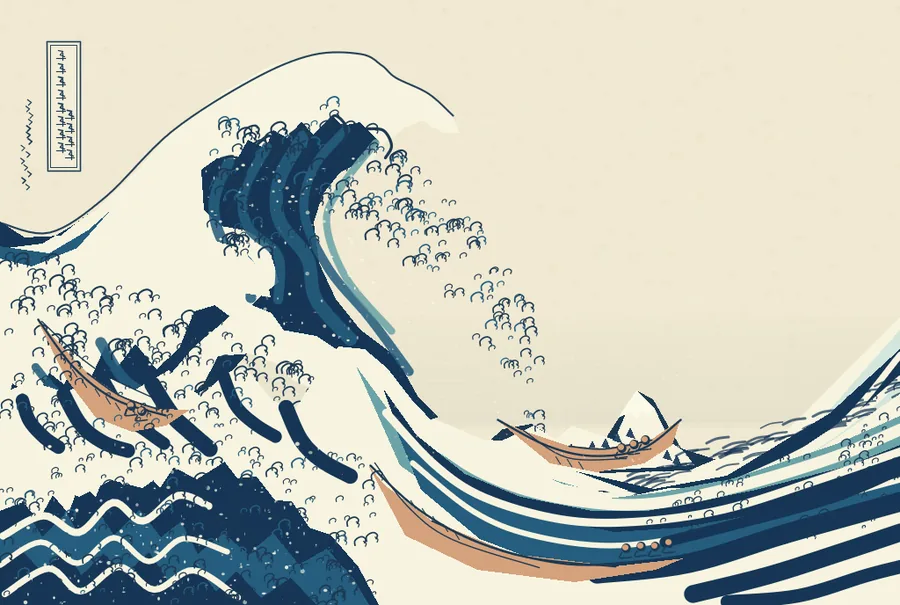
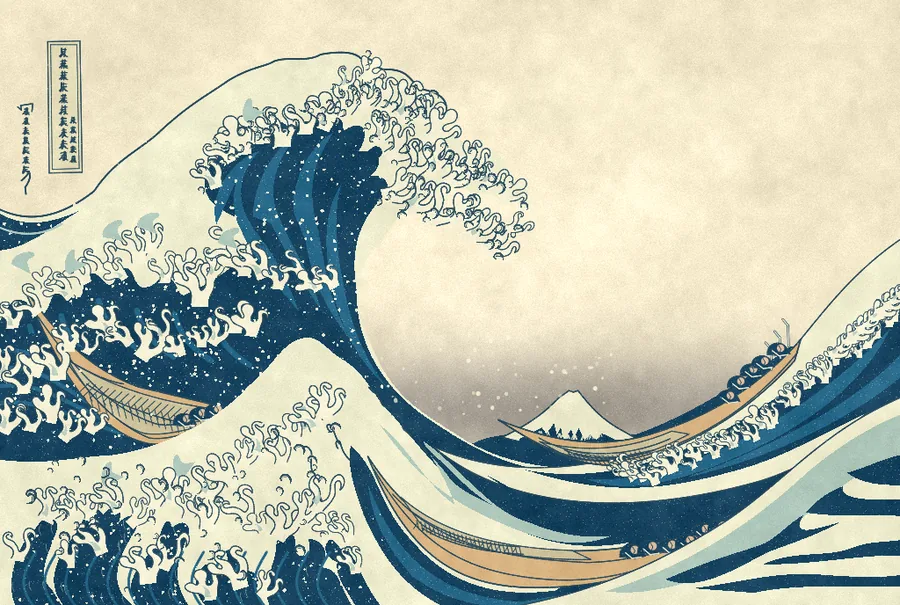
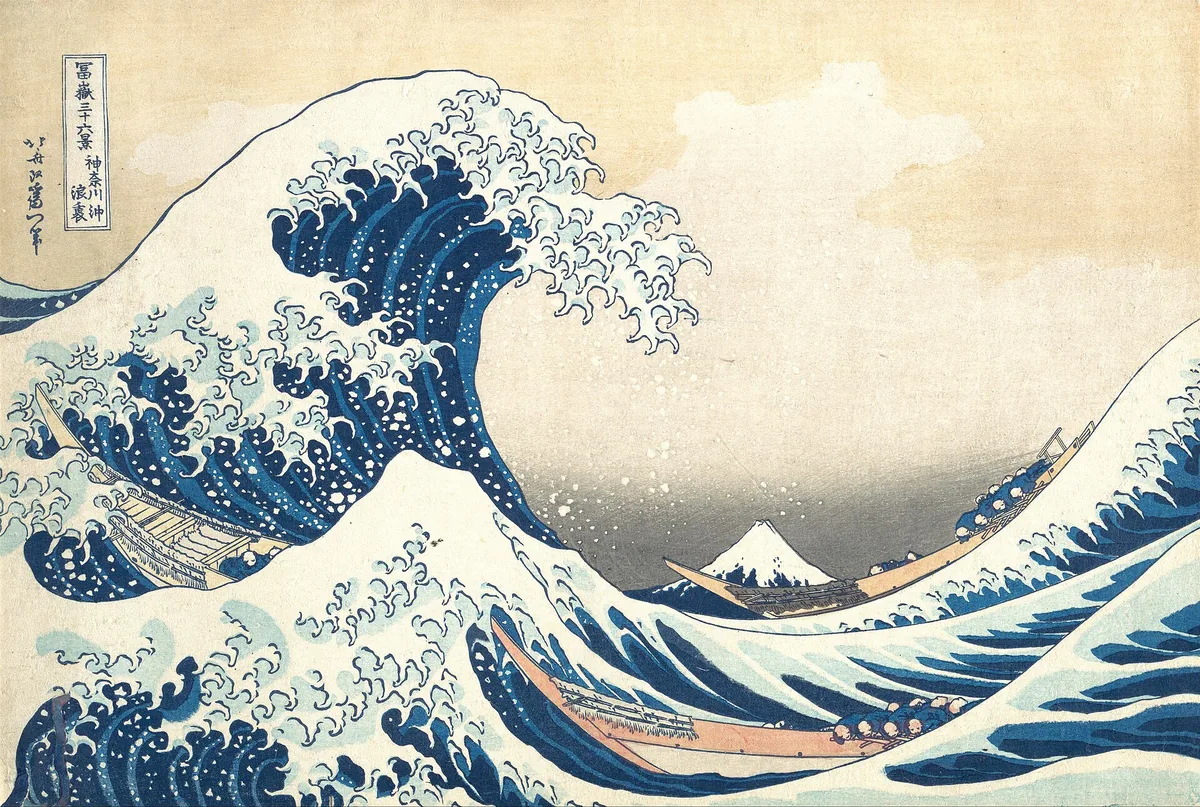
On launch day, Anthropic's staff posted a demo in which models paint a picture by writing their own brush engine in Python, looking at the result and revising. We rebuilt that test and gave it Hokusai's Great Wave, a woodblock print from c. 1830–32. Five models got the same prompt, one run each: Sonnet 5, Sonnet 5.5 and Opus 5.5 in Claude Code, and OpenAI's GPT-6 Sol and GPT-6 Astra in Codex, each on its tool's defaults.

Five models, one prompt, the Great Wave

Hokusai's print, the Great Wave
The printKatsushika Hokusai, Under the Wave off Kanagawa (The Great Wave), c. 1830–32. The Metropolitan Museum of Art, H. O. Havemeyer Collection, Bequest of Mrs. H. O. Havemeyer, 1929 (JP1847). Public domain.
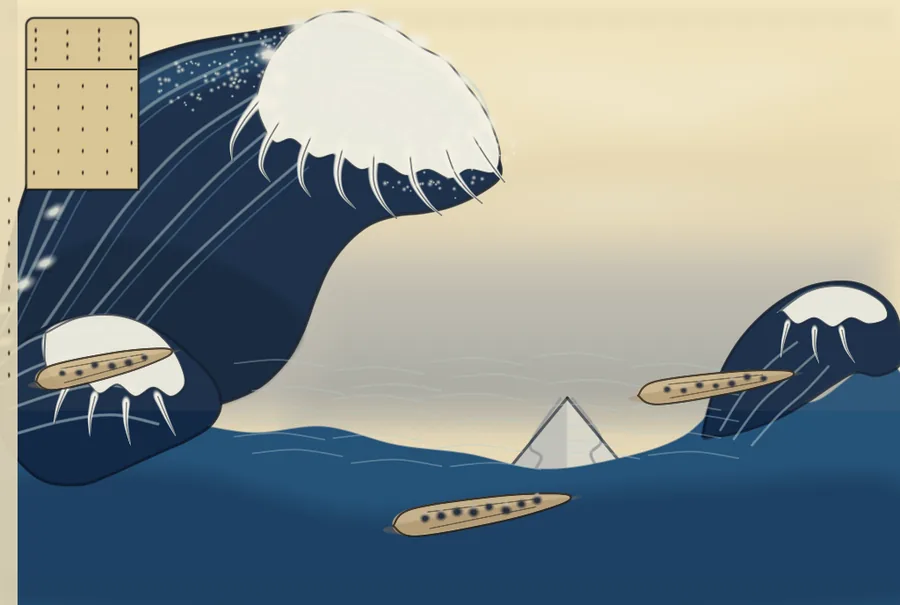
Sonnet 5's painting of the Great Wave
Sonnet 5Claude Code · high · 1 run
66,874 output tokens
Sonnet 5.5's painting of the Great Wave
Sonnet 5.5Claude Code · medium · 1 run
10,660 output tokens
Opus 5.5's painting of the Great Wave
Opus 5.5Claude Code · medium · 1 run
28,600 output tokens
GPT-6 Sol's painting of the Great Wave
GPT-6 SolCodex default · 1 run
tokens not comparable (different tool)
GPT-6 Astra's painting of the Great Wave
GPT-6 AstraCodex default · 1 run
tokens not comparable (different tool)
One run per model on 28 September 2026, with the same prompt for all five. We give output tokens only for the Claude runs, because the OpenAI runs used a different tool and their counts aren't comparable.

Sonnet 5 painted one big, smooth wave. Sonnet 5.5 got the print's blue stripes and its spray. Opus 5.5 got closer to the print, with the foam curling into claws all along the crest, and Astra's painting puts the print's curling foam on every wave.

One run is too few to count tokens by, so we ran each Claude model 5 times, on the Great Wave and on two other pictures. Sonnet 5.5's median run wrote 9,481 output tokens. Sonnet 5's median was 57,847, 6.1× as many, and Opus 5.5's was 21,606, 2.3× as many. The OpenAI runs used a different tool, so their counts aren't comparable and we leave them out.

Output tokens per run, our painting test

Five runs per Claude model: three on one photo, one on the Great Wave, one on a chart. Each model at its Claude Code default

0K20K40K60K80KSonnet 5.5Sonnet 5.5, photo, run 1: 13,785 output tokens · our run, medium, 28 Sep 2026Sonnet 5.5, Great Wave: 10,660 output tokens · our run, medium, 28 Sep 2026Sonnet 5.5, chart: 7,911 output tokens · our run, medium, 28 Sep 2026Sonnet 5.5, photo, run 2: 9,481 output tokens · our run, medium, 28 Sep 2026Sonnet 5.5, photo, run 3: 6,776 output tokens · our run, medium, 28 Sep 20269,481Opus 5.5Opus 5.5, photo, run 1: 18,153 output tokens · our run, medium, 28 Sep 2026Opus 5.5, Great Wave: 28,600 output tokens · our run, medium, 28 Sep 2026Opus 5.5, chart: 22,256 output tokens · our run, medium, 28 Sep 2026Opus 5.5, photo, run 2: 21,606 output tokens · our run, medium, 28 Sep 2026Opus 5.5, photo, run 3: 20,516 output tokens · our run, medium, 28 Sep 202621,606Sonnet 5Sonnet 5, photo, run 1: 43,688 output tokens · our run, high, 28 Sep 2026Sonnet 5, Great Wave: 66,874 output tokens · our run, high, 28 Sep 2026Sonnet 5, chart: 59,499 output tokens · our run, high, 28 Sep 2026Sonnet 5, photo, run 2: 33,996 output tokens · our run, high, 28 Sep 2026Sonnet 5, photo, run 3: 57,847 output tokens · our run, high, 28 Sep 202657,847
Our runs, Claude Code 2.1.284, each model at its default (Sonnet 5 high, Sonnet 5.5 and Opus 5.5 medium), 28 September 2026. The line marks each model's median.
The numbers in this chart
modelphoto, run 1photo, run 2photo, run 3Great Wavechart
Sonnet 5.513,7859,4816,77610,6607,911
Opus 5.518,15321,60620,51628,60022,256
Sonnet 543,68833,99657,84766,87459,499

This says what we saw on one small job, not how the models compare in general. The full painting test gets its own video, and its prompts, runs and numbers will be published with it.

Every setting on Artificial Analysis's index▶ 4:38

One painting job is small. Artificial Analysis ran both Sonnets across its whole Intelligence Index at all five settings, on a pre-release version of Sonnet 5.5, and counted the tokens.

What each setting costs

Cost per task on Artificial Analysis's index, Sonnet 5 against Sonnet 5.5, at each effort setting

Sonnet 5Sonnet 5.5
$2.5$5$7.5$10Sonnet 5 at low: $0.51 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$0.51Sonnet 5.5 at low: $0.41 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$0.41LOWSonnet 5 at medium: $1.00 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$1.00Sonnet 5.5 at medium: $0.59 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$0.59MEDIUM−41%Sonnet 5 at high: $1.79 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$1.79Sonnet 5.5 at high: $1.08 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$1.08HIGHSonnet 5 at xhigh: $2.87 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$2.87Sonnet 5.5 at xhigh: $2.74 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$2.74XHIGHSonnet 5 at max: $5.09 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$5.09Sonnet 5.5 at max: $7.60 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST$7.60MAXcost per task
$2.5$5$7.5$10Sonnet 5 at low: $0.51 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST0.51Sonnet 5.5 at low: $0.41 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST0.41LOWSonnet 5 at medium: $1.00 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST1.00Sonnet 5.5 at medium: $0.59 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST0.59MEDIUM−41%Sonnet 5 at high: $1.79 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST1.79Sonnet 5.5 at high: $1.08 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST1.08HIGHSonnet 5 at xhigh: $2.87 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST2.87Sonnet 5.5 at xhigh: $2.74 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST2.74XHIGHSonnet 5 at max: $5.09 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST5.09Sonnet 5.5 at max: $7.60 cost per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST7.60MAXcost per task
Artificial Analysis Intelligence Index, average per task, list prices including caching. Pre-release deployment of Sonnet 5.5; Artificial Analysis says it will re-run. Read 28 Sep 2026, 21:29 CEST. Re-read 29 Sep 2026, 12:28 CEST: none of the values in this chart has moved.
The numbers in this chart
settingSonnet 5Sonnet 5.5
low$0.51$0.41
medium$1.00$0.59
high$1.79$1.08
xhigh$2.87$2.74
max$5.09$7.60

At low, medium and high, Sonnet 5.5 writes fewer output tokens than Sonnet 5 at the same setting and costs less per task. At medium, the Claude Code default, it costs 41% less per task, $0.59 against $1.00, and it scores 40.7, higher than Sonnet 5 scores at max (38.2). So Anthropic's claim holds on someone else's test.

Above high, that changes. At xhigh the two cost about the same, $2.74 against $2.87. At max, Sonnet 5.5 writes 192.8K output tokens per task, 64% more than Sonnet 5 and the most Artificial Analysis has measured for any model. It costs 49% more per task, $7.60 against $5.09. And max is the setting Anthropic's headline scores came from.

What each setting writes

Output tokens per task on Artificial Analysis's index, Sonnet 5 against Sonnet 5.5

Sonnet 5Sonnet 5.5
62.5K125K187.5K250KSonnet 5 at low: 15.2K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST15.2KSonnet 5.5 at low: 13.9K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST13.9KLOWSonnet 5 at medium: 27.3K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST27.3KSonnet 5.5 at medium: 19.5K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST19.5KMEDIUMSonnet 5 at high: 44.3K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST44.3KSonnet 5.5 at high: 34.5K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST34.5KHIGHSonnet 5 at xhigh: 65.4K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST65.4KSonnet 5.5 at xhigh: 73.7K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST73.7KXHIGHSonnet 5 at max: 117.8K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST117.8KSonnet 5.5 at max: 192.8K output tokens per index task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST192.8KMAX+64%output tokens per task
Artificial Analysis Intelligence Index, average per task, list prices including caching. Pre-release deployment of Sonnet 5.5; Artificial Analysis says it will re-run. Read 28 Sep 2026, 21:29 CEST. Re-read 29 Sep 2026, 12:28 CEST: none of the values in this chart has moved.
The numbers in this chart
settingSonnet 5Sonnet 5.5
low15.2K13.9K
medium27.3K19.5K
high44.3K34.5K
xhigh65.4K73.7K
max117.8K192.8K

Anthropic's own charts at max▶ 5:42

Anthropic's launch page has four charts of score against cost (per attempt on Terminal-Bench, per task on the other three), and on all four, Sonnet 5.5 at max costs more than Sonnet 5 at max.

Anthropic's own charts, both Sonnets at max

Cost at max effort on the four charts of Anthropic's launch page: per attempt on Terminal-Bench, per task on the other three

Sonnet 5Sonnet 5.5
Terminal-Bench 4.0Terminal-Bench 4.0, Sonnet 5 at max: $11.64 per attempt (read off Anthropic's chart, approximate)$11.64Sonnet 5Terminal-Bench 4.0, Sonnet 5.5 at max: $12.56 per attempt (read off Anthropic's chart, approximate)$12.56Sonnet 5.5FrontierCode v1.1FrontierCode v1.1, Sonnet 5 at max: $17.03 per task (read off Anthropic's chart, approximate)$17.03Sonnet 5FrontierCode v1.1, Sonnet 5.5 at max: $20.73 per task (read off Anthropic's chart, approximate)$20.73Sonnet 5.5CursorBench 4.0CursorBench 4.0, Sonnet 5 at max: $7.18 per task (read off Anthropic's chart, approximate)$7.18Sonnet 5CursorBench 4.0, Sonnet 5.5 at max: $9.70 per task (read off Anthropic's chart, approximate)$9.70Sonnet 5.5AA-Briefcase v1.1AA-Briefcase v1.1, Sonnet 5 at max: $14.41 per task (read off Anthropic's chart, approximate)$14.41Sonnet 5AA-Briefcase v1.1, Sonnet 5.5 at max: $29.16 per task (read off Anthropic's chart, approximate)$29.16Sonnet 5.5
Redrawn from Anthropic's launch page; values read off the chart, so approximate. Page read 28 Sep 2026, 21:17 CEST.
The numbers in this chart
chartSonnet 5 at maxSonnet 5.5 at max
Terminal-Bench 4.0 (per attempt)$11.64$12.56
FrontierCode v1.1 (per task)$17.03$20.73
CursorBench 4.0 (per task)$7.18$9.70
AA-Briefcase v1.1 (per task)$14.41$29.16

On FrontierCode, a test of whether a code change would get merged, Sonnet 5.5 scores lower at max than at xhigh, 46.2% against 52.1% on Anthropic's table, while costing about 13× as much, $20.73 a task against $1.59. The costs are read off Anthropic's chart, so they are approximate. Anthropic's footnote says that at max it more often ran a code-review skill that splits the work across many subagents. Cognition, which ran that test, looked at two cases where this led to a timeout or to edits outside the task, and so to a lower score.

One prompt at max: the pelican▶ 6:23

Simon Willison's standard test for new models is an SVG of a pelican riding a bicycle, and he ran Sonnet 5.5 at all five settings.

One prompt, five settings

Sonnet 5.5 drawing “an SVG of a pelican riding a bicycle”, one run per setting

settingtimeoutput tokensresult
low10s1,623a pelican
medium11s1,796a pelican
high17s2,334a pelican
xhigh41s5,730a pelican
max15m 40s128,000failed to return response
Simon Willison, on Hacker News. Read 28 Sep 2026, 21:27 CEST.

Low took 10s and medium 11s, high 17s and xhigh 41s. At max it thought for 15m 40s, hit the limit for a single response, 128,000 output tokens, and returned no pelican at all.

Which setting to use▶ 6:56

At medium, Sonnet 5.5 is a straight upgrade on Sonnet 5. It scores higher and costs less per task on Artificial Analysis's index and on all four of Anthropic's charts. At high, the API's default, the same is true on all but one chart, AA-Briefcase, where it costs a little more: $3.96 a task against $3.77.

Even at the Claude Code default, Opus 5.5 is worth comparing on Artificial Analysis's index. Opus 5.5 at low scores slightly higher than Sonnet 5.5 at medium for slightly less: 42.3 against 40.7, at $0.55 a task against $0.59. At high, no Opus 5.5 setting scores higher than Sonnet 5.5 for less.

Above high, the gap in Opus 5.5's favour grows. On Artificial Analysis's index, Opus 5.5 at medium scores about the same as Sonnet 5.5 at xhigh, 51.2 against 51.9, for about half the cost: $1.34 a task against $2.74. Opus 5.5 at xhigh matches Sonnet 5.5 at max, 56.0 against 56.0, for less than half: $3.46 against $7.60.

What to run it at

Intelligence Index score against cost per task, each model at its five effort settings

Sonnet 5.5Sonnet 5Opus 5.5GPT-6 Sol
2030405060$0.10$0.30$1$3$10Sonnet 5.5 at low: score 35.8, $0.41 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTlowSonnet 5.5 at medium: score 40.7, $0.59 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTmediumSonnet 5.5 at high: score 46.7, $1.08 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESThighSonnet 5.5 at xhigh: score 51.9, $2.74 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTxhighSonnet 5.5 at max: score 56.0, $7.60 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTmaxSonnet 5.5Sonnet 5 at low: score 24.3, $0.51 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at medium: score 28.1, $1.00 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at high: score 31.7, $1.79 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at xhigh: score 34.4, $2.87 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at max: score 38.2, $5.09 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5Opus 5.5 at low: score 42.3, $0.55 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at medium: score 51.2, $1.34 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at high: score 53.6, $1.82 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at xhigh: score 56.0, $3.46 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at max: score 57.6, $5.98 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5GPT-6 Sol at low: score 33.9, $0.13 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTGPT-6 Sol at medium: score 39.8, $0.25 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTGPT-6 Sol at high: score 42.8, $0.37 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $0.38 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Sol at xhigh: score 44.1, $0.53 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $0.52 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Sol at max: score 47.5, $1.06 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $1.05 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Solscorecost per task, log scale
2030405060$0.10$0.30$1$3$10Sonnet 5.5 at low: score 35.8, $0.41 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5.5 at medium: score 40.7, $0.59 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5.5 at high: score 46.7, $1.08 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5.5 at xhigh: score 51.9, $2.74 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5.5 at max: score 56.0, $7.60 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5.5Sonnet 5 at low: score 24.3, $0.51 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at medium: score 28.1, $1.00 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at high: score 31.7, $1.79 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at xhigh: score 34.4, $2.87 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5 at max: score 38.2, $5.09 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTSonnet 5Opus 5.5 at low: score 42.3, $0.55 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at medium: score 51.2, $1.34 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at high: score 53.6, $1.82 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at xhigh: score 56.0, $3.46 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5 at max: score 57.6, $5.98 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTOpus 5.5GPT-6 Sol at low: score 33.9, $0.13 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTGPT-6 Sol at medium: score 39.8, $0.25 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CESTGPT-6 Sol at high: score 42.8, $0.37 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $0.38 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Sol at xhigh: score 44.1, $0.53 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $0.52 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Sol at max: score 47.5, $1.06 per task · Artificial Analysis, read 28 Sep 2026, 21:29 CEST · cost now $1.05 (re-read 29 Sep 2026, 12:28 CEST)GPT-6 Solscorecost per task, log scale
Artificial Analysis Intelligence Index, average per task, list prices including caching. Pre-release deployment of Sonnet 5.5; Artificial Analysis says it will re-run. Read 28 Sep 2026, 21:29 CEST. Re-read 29 Sep 2026, 12:28 CEST: 3 values in this chart have moved since, all GPT-6 Sol's cost per index task; the numbers table below has them.
The numbers in this chart
settingSonnet 5.5 scoreSonnet 5.5 cost per index taskSonnet 5 scoreSonnet 5 cost per index taskOpus 5.5 scoreOpus 5.5 cost per index taskGPT-6 Sol scoreGPT-6 Sol cost per index task
low35.8$0.4124.3$0.5142.3$0.5533.9$0.13
medium40.7$0.5928.1$1.0051.2$1.3439.8$0.25
high46.7$1.0831.7$1.7953.6$1.8242.8$0.37now $0.38
xhigh51.9$2.7434.4$2.8756.0$3.4644.1$0.53now $0.52
max56.0$7.6038.2$5.0957.6$5.9847.5$1.06now $1.05

Most of the difference is cache reads. At those settings Sonnet 5.5 reads 3.6× and 3.2× as much from its cache as Opus 5.5, and cache reads cost $0.20 per million tokens on both, so Opus's higher price doesn't apply there. Of the $1.41 gap per task between Sonnet 5.5 at xhigh and Opus 5.5 at medium, $1.07 is cache reads and $0.22 is output; of the $4.14 gap between Sonnet 5.5 at max and Opus 5.5 at xhigh, $3.04 is cache reads and $0.62 is output. Opus 5.5 costs twice as much per token it writes, but Sonnet 5.5 writes about three times as many (2.9× and 2.9×), which cancels most of that. So if a job needs Sonnet 5.5 at xhigh or max, try Opus 5.5 a step or two lower first.

If you're not tied to Anthropic, OpenAI's GPT-6 Sol has, on the same index, a setting that scores higher for less than each of Sonnet 5.5's settings from low to high. At low and medium it is much cheaper: Sol at medium scores 39.8 for $0.25 a task against Sonnet 5.5 at low with 35.8 for $0.41 (40% less), and Sol at high scores 42.8 for $0.37now $0.38 against Sonnet 5.5 at medium with 40.7 for $0.59 (36% less). At high the two cost about the same: Sol at max scores 47.5 for $1.06now $1.05, against Sonnet 5.5 at high with 46.7 for $1.08.

If you do security work, Anthropic says "higher-risk cybersecurity tasks will visibly fall back to Sonnet 5." On Anthropic's own API that fallback is a beta option you switch on. Without it, those requests are refused.

If you pay with a plan▶ 8:39

All of that is in API dollars. If you pay for a Claude plan instead, Anthropic's ClaudeDevs account on X says Sonnet 5.5 means "your Claude Code usage goes further". None of the Anthropic pages we saved on launch day (the launch page, the Sonnet product page and the migration guide, read 28 September) says how plan usage is counted for Sonnet against Opus, so from those pages, nobody can say how much further.

Who's talking on launch day▶ 9:02

Most of the launch-day posts you'll see aren't measurements. The biggest are Anthropic's own and its staff's. Then come people who had the model early: Matthew Berman and two editors from his channel, and Alex Finn, who wrote that at first he couldn't tell it apart from Opus 5.5. Then come companies quoted on Anthropic's launch page, such as Box and Every, posting their own results.

One of those posts is useful. Kieran Klaassen, who works at Every, says to run it on low or medium, and to move to Opus if a job needs more. Artificial Analysis's numbers agree with him at medium, by a small margin: Opus 5.5 at low scores 42.3 against 40.7, at $0.55 a task against $0.59. At high they don't: no Opus 5.5 setting scores higher than Sonnet 5.5 for less.

What nobody has measured yet▶ 9:48

None of this tells you how Sonnet 5.5 does on your own work, at the setting you use. Artificial Analysis ran a pre-release version that Anthropic found had a bug with structured outputs, and it says it will re-run. Our painting test is one small job. And when we made the video, we hadn't found anyone outside Anthropic who had published the comparison that would settle it: everyday work, like a long coding session, at each setting, run more than once, with the tokens counted.

Five days before Sonnet 5.5, Fireworks released a model called Ember-1 that makes the same promise: "half the tokens, same answers". That's our next video.

Every number

These are all 304 figures behind the video and this page, grouped by whose they are, with the page each came from and when we read it. Figures marked ⟳ can move. When a re-read finds a change, the new value shows next to the one from the video.

Artificial Analysis Intelligence Index, by effort setting

Artificial Analysis · Artificial Analysis, Claude Sonnet 5.5 model page (every effort setting) · read 28 Sep 2026, 21:29 CEST · ⟳ re-read 29 Sep 2026, 12:28 CEST, 7 moved · Run on a pre-release deployment of Sonnet 5.5; Artificial Analysis says it will re-run.

Intelligence index score

lowmediumhighxhighmax
Sonnet 5.535.840.746.751.956.0
Sonnet 524.328.131.734.438.2
Opus 5.542.351.253.656.057.6
GPT-6 Sol33.939.842.844.147.5

Cost per index task, list prices incl. caching

Output tokens per index task

Anthropic's cost-per-task charts, values read off the chart (approximate)

Terminal-Bench 4.0: score at cost per task

lowmediumhighxhighmax
Sonnet 5.520.0% at $0.7628.7% at $0.8343.0% at $1.9461.5% at $5.3170.5% at $12.56
Sonnet 53.2% at $3.774.4% at $4.834.4% at $8.217.0% at $9.9610.4% at $11.64
Opus 5.538.6% at $1.2957.6% at $2.9464.2% at $3.8966.4% at $7.3564.7% at $11.25
GPT Sol (5.6 or 6, per chart legend)7.8% at $1.4620.9% at $2.6926.2% at $4.1228.5% at $5.3937.2% at $7.90

FrontierCode v1.1: score at cost per task

lowmediumhighxhighmax
Sonnet 5.529.3% at $0.1936.5% at $0.2449.4% at $0.4252.1% at $1.5946.2% at $20.73
Sonnet 528.7% at $2.3835.2% at $3.8139.4% at $6.0942.7% at $10.0342.4% at $17.03
Opus 5.547.3% at $0.4054.7% at $0.8054.0% at $1.0951.4% at $2.2454.4% at $6.16
GPT Sol (5.6 or 6, per chart legend)37.3% at $0.4345.9% at $0.7647.7% at $1.0448.4% at $1.3249.3% at $2.06

CursorBench 4.0: score at cost per task

lowmediumhighxhighmax
Sonnet 5.535.8% at $0.5039.2% at $0.7047.8% at $1.6753.2% at $3.8955.5% at $9.70
Sonnet 524.1% at $1.3928.0% at $2.3130.8% at $3.4832.0% at $4.5634.1% at $7.18
Opus 5.543.7% at $1.1752.6% at $2.9156.0% at $3.9856.0% at $6.9957.9% at $13.46
GPT Sol (5.6 or 6, per chart legend)24.6% at $0.8731.1% at $1.7735.7% at $2.8537.8% at $4.4141.8% at $8.24

AA-Briefcase v1.1: score at cost per task

lowmediumhighxhighmax
Sonnet 5.51265 at $0.871461 at $1.641634 at $3.961746 at $9.611811 at $29.16
Sonnet 5922 at $0.821056 at $1.731178 at $3.771275 at $7.531359 at $14.41
Opus 5.51285 at $1.151642 at $4.401704 at $6.281781 at $12.271823 at $21.00
GPT Sol (5.6 or 6, per chart legend)905 at $0.121143 at $0.341290 at $0.631364 at $1.191483 at $2.66

Our token runs, output tokens per run

Model Fatigue (our runs) · Our Great Wave runs and token runs (Claude Code 2.1.284 and Codex, each tool's defaults) · run 28 Sep 2026, 21:15–22:41 CEST (start times of the fifteen runs)
photo, run 1photo, run 2photo, run 3Great Wavechart
Sonnet 5.513,7859,4816,77610,6607,911
Sonnet 543,68833,99657,84766,87459,499
Opus 5.518,15321,60620,51628,60022,256

Anthropic

Introducing Claude Sonnet 5.5 (launch page) · read 28 Sep 2026, 21:17 CEST
Sonnet 5.5 price per million input tokens$2
Sonnet 5.5 price per million output tokens$10
cache reads per million tokens, Sonnet 5.5 and Opus 5.5 alike$0.20
Opus 5.5 price per million input tokens$4
Opus 5.5 price per million output tokens$20
how much faster Sonnet 5.5 writes output than Sonnet 5, per Anthropic30%+
Anthropic's "up to" saving per task against Sonnet 530%
Terminal-Bench 4.0, Sonnet 5.5 at max (Anthropic's table)70.6%
Terminal-Bench 4.0, Sonnet 5 (Anthropic's table)10.3%
Terminal-Bench 4.0, Opus 5.5 at xhigh, its highest score (Anthropic's table)66.4%
GDPval-AA v2.1 Elo, Sonnet 5.5 at max1844
GDPval-AA v2.1 Elo, Opus 5.51846
FrontierCode 1.1, Sonnet 5.5 at max (Anthropic's table)46.2%
FrontierCode 1.1, Sonnet 5.5 at xhigh (Anthropic's table)52.1%
Sonnet 5.5 at max minus Opus 5.5 at xhigh, Terminal-Bench 4.04.2 points

Anthropic

Claude Sonnet 5.5 System Card · read 28 Sep 2026, 21:17 CEST
GDPval-AA Elo, Sonnet 5.5 at xhigh (system card §8.14.3)1725
fewer output tokens at xhigh than at max on GDPval-AA (system card §8.14.3)67%
standard error of the Terminal-Bench 4.0 score, Sonnet 5.5 (system card §8.5)±2.5
standard error of the Terminal-Bench 4.0 score, Opus 5.5 (system card §8.5)±2.6
Terminal-Bench 4.0 trials where a request went to a fallback model, Sonnet 5.5 (system card §8.5)1.5%
Terminal-Bench 4.0 trials where a flagged request was answered by an older model, Opus 5.5 (system card §8.5)10%

Artificial Analysis

output tokens per index task at max, "the highest token use we have measured"~193k
rank on the Intelligence Index, at max#2

Vals AI

Vals AI, Claude Sonnet 5.5 · read 28 Sep 2026, 21:24 CEST
rank on the Vals Index#2
models ranked on the Vals Index66
Vals Index, Sonnet 5.569.22%
Vals Index, Opus 5.569.69%
Vals's error bar on Sonnet 5.5's Vals Index score±0.96

Simon Willison

time for the pelican at low10s
time for the pelican at medium11s
time for the pelican at high17s
time for the pelican at xhigh41s
time at max, until the response failed15m 40s
output tokens for the pelican at low1,623
output tokens for the pelican at medium1,796
output tokens for the pelican at high2,334
output tokens for the pelican at xhigh5,730
output tokens at max, the limit for one response128,000

Model Fatigue (our runs)

Our Great Wave runs and token runs (Claude Code 2.1.284 and Codex, each tool's defaults) · run 28 Sep 2026, 21:15–22:41 CEST (start times of the fifteen runs)
output tokens, Sonnet 5 painting the Great Wave, 1 run, Claude Code default (high)66,874
output tokens, Sonnet 5.5 painting the Great Wave, 1 run, Claude Code default (medium)10,660
output tokens, Opus 5.5 painting the Great Wave, 1 run, Claude Code default (medium)28,600
token runs per Claude model (3 on one photo, the Great Wave, a chart)5
median output tokens over 5 runs, Sonnet 5.59,481
median output tokens over 5 runs, Sonnet 557,847
median output tokens over 5 runs, Opus 5.521,606
Sonnet 5's median over Sonnet 5.5's6.1×
Opus 5.5's median over Sonnet 5.5's2.3×

The Metropolitan Museum of Art

when the print was first publishedc. 1830–32

Artificial Analysis

cost per task, Sonnet 5.5 against Sonnet 5, both at low−19% ⟳
cost per task, Sonnet 5.5 against Sonnet 5, both at medium−41% ⟳
cost per task, Sonnet 5.5 against Sonnet 5, both at high−40% ⟳
cost per task, Sonnet 5.5 against Sonnet 5, both at xhigh−5% ⟳
cost per task, Sonnet 5.5 against Sonnet 5, both at max+49% ⟳
output tokens per task, Sonnet 5.5 against Sonnet 5, both at max+64% ⟳
cost per task, Opus 5.5 at medium as a share of Sonnet 5.5 at xhigh0.49× ⟳
cost per task, Opus 5.5 at xhigh as a share of Sonnet 5.5 at max0.45× ⟳
output tokens per task, Sonnet 5.5 at xhigh over Opus 5.5 at medium2.9× ⟳
output tokens per task, Sonnet 5.5 at max over Opus 5.5 at xhigh2.9× ⟳
cost per task, GPT-6 Sol at medium against Sonnet 5.5 at low−40% ⟳
cost per task, GPT-6 Sol at high against Sonnet 5.5 at medium−36% ⟳

Artificial Analysis

cache reads per task, Sonnet 5.5 at xhigh over Opus 5.5 at medium (cache reads cost the same on both)3.6×
cache reads per task, Sonnet 5.5 at max over Opus 5.5 at xhigh3.2×
cost per index task, Sonnet 5.5 at xhigh minus Opus 5.5 at medium$1.41
of that gap, cache reads$1.07
of that gap, output tokens$0.22
cost per index task, Sonnet 5.5 at max minus Opus 5.5 at xhigh$4.14
of that gap, cache reads$3.04
of that gap, output tokens$0.62

Anthropic

FrontierCode cost per task, Sonnet 5.5 at max over xhigh (read off the chart)13×

Sources

These are the pages the video and this page draw on. We keep a copy of each page as we read it, so a figure can be checked against what the page said at the time.
Credits

The narration in the video is an AI voice, made with ElevenLabs.

Numbers read off Anthropic's charts are approximate.